





// Recruitment Technology
Your CRM Record Model Is Fighting Reality
Published: 01 October 2026,
9 min to read
The bottom line
Most recruitment systems force a choice the moment a record is created: candidate or contact. Agencies answer it twice. One person then holds two profiles, with the relationship history split between them. A single-person record model gives your team one full history instead of two half-truths.
A record model decision hiding inside your candidate database
The best candidate you placed three years ago now signs off your terms of business. Your system holds two records for her. One says candidate, the other says client contact. Neither knows the other exists.
Blame the architecture rather than your team’s discipline. Your recruitment CRM asked a question the real world refuses to answer cleanly. Every record created since has inherited that answer. Fifty-four agencies raised some version of this with us on recorded calls. Most described the same remedy: one person merging duplicates by hand on a Friday afternoon.
The cost never appears as a line item. It shows up as a spec CV sent to a contact who rejected that candidate. It shows up as a BD call opening cold on somebody your colleague placed. It shows up as a Boolean search that misses your best passive candidate. And it shows up as a fall-off nobody predicted, because the signs sat on the other record.
Why does your recruitment CRM store one person as two records?
Because the software made you choose. Most platforms rest on a split foundation. The applicant tracking system models a job seeker moving through a pipeline. The CRM models a buyer moving through a sales cycle. Those are two objects with two field sets. Anyone who is both gets entered twice.
The split was defensible twenty years ago. An ATS tracked applications against live roles. A CRM tracked accounts and opportunities. The two rarely needed to know about each other. Agencies bought them separately, or bought one product that joined them at the interface. The tables stayed apart underneath.
Recruitment stopped working that way. In executive search, the candidate list and the client list describe the same market. On a contract desk, the finisher you place this month briefs you as a site manager next quarter. Rec2rec is the purest version, where every contact is both a placement target and a buyer.
So the duplicate is not your recruiters being careless. It is the correct response to a system with one dropdown and two mutually exclusive options.
What does a split candidate record cost your desk?
It costs you the two things a candidate database exists for. Finding the right person, and knowing what happened last time. When someone exists twice, every search returns a fraction of them. Your consultant acts on whichever record they opened first.
Take the search problem. A consultant runs a market map and works the results. The candidate record holds the skills, the salary expectation, the notice period, and the interview notes. The contact record holds the current job title that matches the brief. Neither half answers the question alone. Nobody finds out what the search missed.
Split records also go stale faster. A change captured on one profile never reaches its twin. That is how data decay quietly removes your easiest placements from view.
Then the history problem, which compounds. Gartner puts the average annual cost of poor data quality at $12.9 million per organization. The more telling figure in the same research: 59% of organizations do not measure data quality at all. Work in MIT Sloan Management Review puts the cost of bad data at 15% to 25% of revenue. Agencies pay it as rework. The same person qualified twice. The same market mapped twice. The same relationship rebuilt by whoever inherits the desk.
The internal experience of this is well measured. 56.16% of agency recruiters describe their recruitment technology setup as functional but fragmented. A record model that halves people is fragmentation inside one system rather than across several. There is a compliance edge too. A deletion request that clears one profile and leaves its twin behind is a documented gap.
How should a single-person record model handle candidate and client data?
One record per human being, with roles layered on top. The person becomes the permanent object in your database. Candidate, client contact, referrer, and former placement become roles that one record holds at once.
In practice, the model has to deliver five things before a recruiter will trust it.
None of this asks your team to work harder at data entry. It asks the layer underneath to stop posing a question with no correct answer. That also explains why CRM adoption fails at recruitment agencies. Recruiters resist maintaining data the platform should hold itself.
- One identity, many roles. The same person can be shortlisted in the morning and take a BD call after lunch.
- One timeline. Calls, emails, interview notes, spec CV sends, and fee conversations sit in one chronological history.
- One search index. A query returns the person once, scored on everything known about them.
- One compliance position. Consent, retention, deletion requests, and rebate period detail attach to a person rather than two partial copies.
- One set of numbers. Submission-to-interview and send-to-placement ratios stop double counting people who exist twice.
Can AI agents keep one relationship history clean without manual merging?
Yes, and this is the part a legacy model cannot retrofit. Keeping one record accurate means capturing every interaction automatically. It also means revising that record when someone’s situation changes. The work is continuous, and no recruiter will do it by hand at volume.
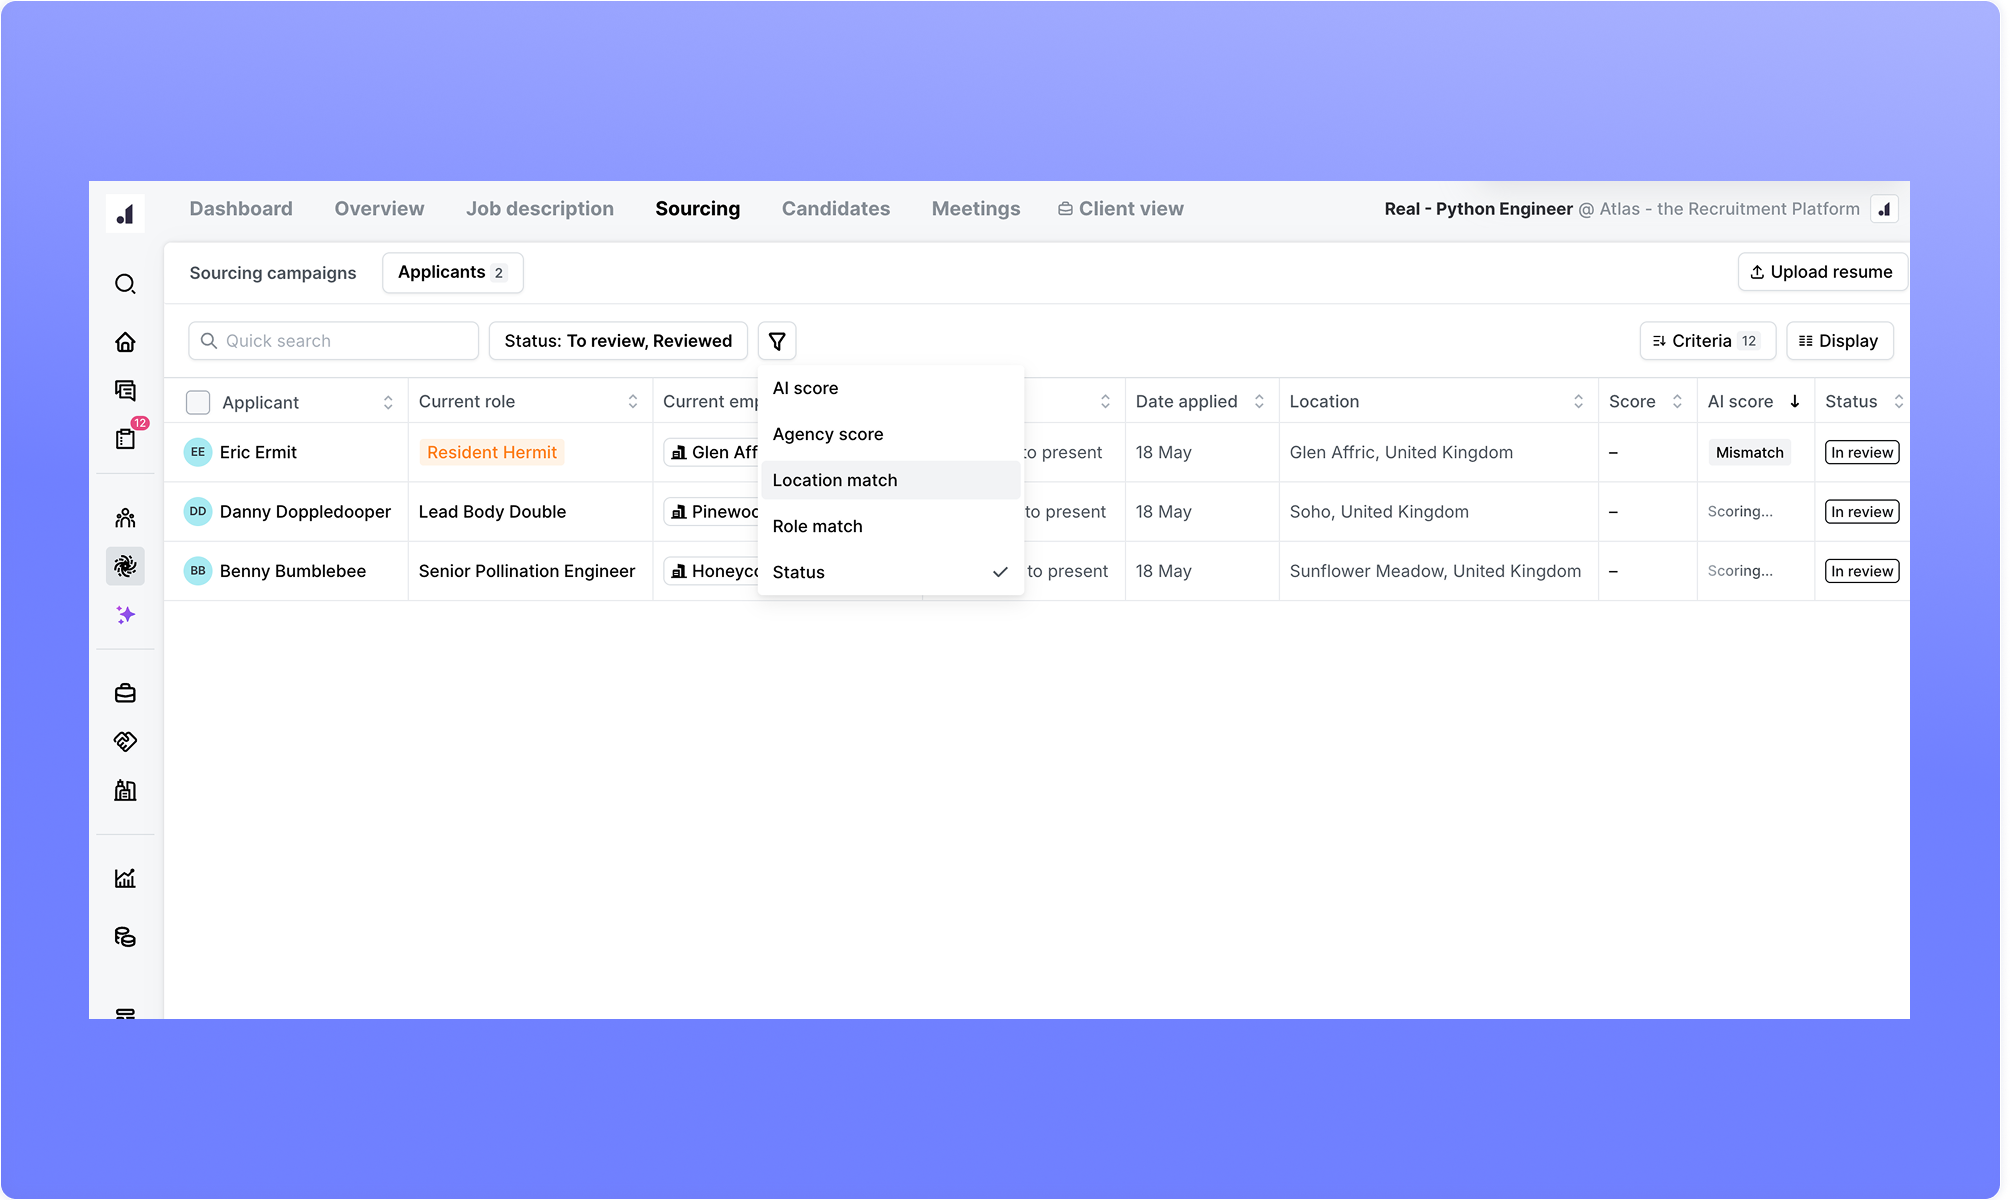
Taking that work off the desk is the design goal behind Atlas. It is an AI-powered CRM and recruitment platform that uses agentic AI to remove admin. Rather than asking a recruiter to classify a person, the AI-powered CRM connects to Gmail and Outlook. Every person your team has ever emailed lands in the database. Candidate and client records then stay current on their own.
The record also keeps itself honest. A swarm of AI agents runs in the background. They track role and company changes across your network in real time, updating candidate records as people move. The placed candidate who becomes a hiring manager is exactly the event that design catches. CV parsing on arrival means the profile underneath is structured without anyone touching a field.
Everything your team says, hears, reads, and writes lands in one place through Total Memory. It captures phone calls, video meetings, emails, notes, and WhatsApp messages into one searchable history. Search then works the way recruiters already assume it does. A plain-language query against your recruitment database software reaches every candidate your team has ever sourced, placed, emailed, or spoken to.
The commercial effect shows on small desks as well as large ones. One managing director watched most of his daily communication never reach his old system. After moving, his agency recorded 80% less time spent on CV formatting and related admin. Role capacity rose from five to eight live roles at once to fifteen to twenty.
Frequently asked questions (FAQs) on recruitment CRM record models
It is a data model where each person has exactly one record. Their relationship to your agency is expressed as roles that record holds at the same time. The same person can be a candidate on one search and a client contact on another. Notes, emails, calls, and placement history all attach to that single record.
Because most platforms were built on separate ATS and CRM foundations. A candidate and a contact are different object types with different fields. When a person is both, the system cannot represent that, so a recruiter creates a second profile. The duplicate is a product of the architecture rather than careless data entry.
Merging cleans up history, but it does not stop new duplicates appearing. The condition that created them is still in place. Agencies relying on periodic merges are managing a symptom on a schedule. A record model that lets one person hold several roles removes the cause.
It simplifies both. Consent, retention periods, deletion requests, and rebate records apply to a person. Acting on one request then covers everything you hold about them. When someone exists on two records, clearing one leaves data you were asked to delete.
It usually improves it. Duplicate people inflate database size and distort your ratios. Submission-to-interview and send-to-placement both count the same individual more than once. Reporting on unique people gives managers numbers they can act on. Expect the headline record count to fall during migration.
Only partially. Deduplication tools, validation rules, naming conventions, and periodic audits reduce the volume, and all are worth running. They cannot change what the underlying schema permits. If the platform demands a candidate or a contact, new duplicates keep arriving.
Life on the desk after the duplicates disappear
The record model is the quietest decision in your recruitment CRM, and it shapes everything downstream. It sets what your consultants can find and what they know before they dial. It also sets how much of the week goes to reconciling two versions of one relationship. Fixing it at the data layer removes a whole category of work.
Picture the week after the change. Nobody opens a second profile to check for history elsewhere. Nobody runs a deduplication pass. A consultant picking up a lapsed key account reads one continuous story. Delivering that day to day is what Atlas was built for. Agentic AI captures the interactions and keeps records current. Recruiters spend their hours on calls, shortlists, client meetings, and fees.
If your team spends part of every week reconciling duplicate people, that time is worth seeing back on the desk.