





// Recruitment Technology
Test AI Candidate Search on Your Own Database First
Published: 19 October 2026,
8 min to read
The bottom line
Search quality cannot be judged on a vendor’s data, because the demo database was built to make the search look good. The only valid test is a live role run against your own records, benchmarked against the Boolean your team already writes. That test answers a harder question too: whether the weak link is the search or the candidate data under it.
Demo conditions versus the conditions on your desk
Candidate search AI demos run on a database that has never had a bad day. Every record is parsed. Every one of the job titles is standardized. Nobody appears three times under two spellings of their own surname.
Your database is not that one. It carries a decade of imports, at least one merger, two naming conventions, and a consultant who tagged everything as potential. A few thousand resumes arrived as PDFs nobody ever parsed. Older records also decay quietly while nobody is looking, which thins the talent pool long before anyone notices.
So the real question is whether a platform can search well across fifteen years of your team’s habits. Only your own candidate data answers that. Agency leaders tell us the same thing repeatedly, and they tell us often: the demo never predicted the first week.
Why does candidate search AI look so good on someone else’s data?
Because the demo is a controlled environment and every variable in it was chosen for you. The role is one the vendor has run a hundred times. The candidate profiles are complete. The person driving knows precisely which phrasing the model rewards.
That is not dishonesty. It is a product demonstration working exactly as intended. The trouble starts when a buying team treats a controlled result as evidence about an uncontrolled desk.
The cost of that confusion is measurable. 56% of organizations report a high degree of regret over their largest tech purchase. Gartner found that regret peaked among buyers who had not yet started implementation. Enthusiasm at signature says little about month three.
Scale adds a second problem the demo cannot show. Past twenty recruiters, search consistency across teams and verticals matters more than any single result. One consultant getting a brilliant list from one brief proves nothing about forty people phrasing it forty ways.
How should you run a live role through the search?
Take a role you are working right now and run it end to end. Your own records, your own consultant driving. Anything less is a product tour.
The point is to produce a result the buying team can argue about afterward. That means fixing the variables before you start rather than after you see the output.
Let the person who owns the desk drive, not the vendor and not your ops lead. CRM adoption fails at agencies far more often through rollout than through missing features, and search behaves the same way. A tool that only works in expert hands will not survive contact with a full desk.
Two roles, two verticals, two consultants. The whole exercise costs less than a day and settles arguments that otherwise run for six weeks.
- Pick a live role you have already filled or are filling now, so you know what a good answer looks like.
- Load real records, duplicates and half-parsed resumes included. A cleaned sample measures the vendor’s parsing, not your search.
- Write the brief once and use the identical wording in every system you are testing, so the search runs on the same criteria.
- Capture the first twenty results, the time taken, the reason given for each match, and anything the system got obviously wrong.
- Repeat on a second role in a different vertical, because one search is an anecdote rather than a finding.
Which results do you benchmark against your existing Boolean search?
Benchmark against the Boolean string your team would have written for the same brief. It is the only baseline with authority, because it represents the standard your desk already hits.
Run both, then compare four columns: the overlap, the unique finds on each side, the shared misses, and the time taken. Overlap tells you the AI matching is at least competent. The unique finds are where the commercial value sits. The shared misses are the most interesting column. Those people usually sit in your existing ATS, unreachable by either route.
Then score the top twenty the way you would score a longlist. How many would a consultant actually call? A tool that returns 200 plausible profiles and six qualified candidates has not saved anyone recruiter time. Natural language candidate search earns the switch only if the top of the list holds up under that test.
The upside when it does hold up is not subtle. Novify cut shortlist delivery by 96% after moving onto Atlas, alongside more than 20 hours of admin saved every month.
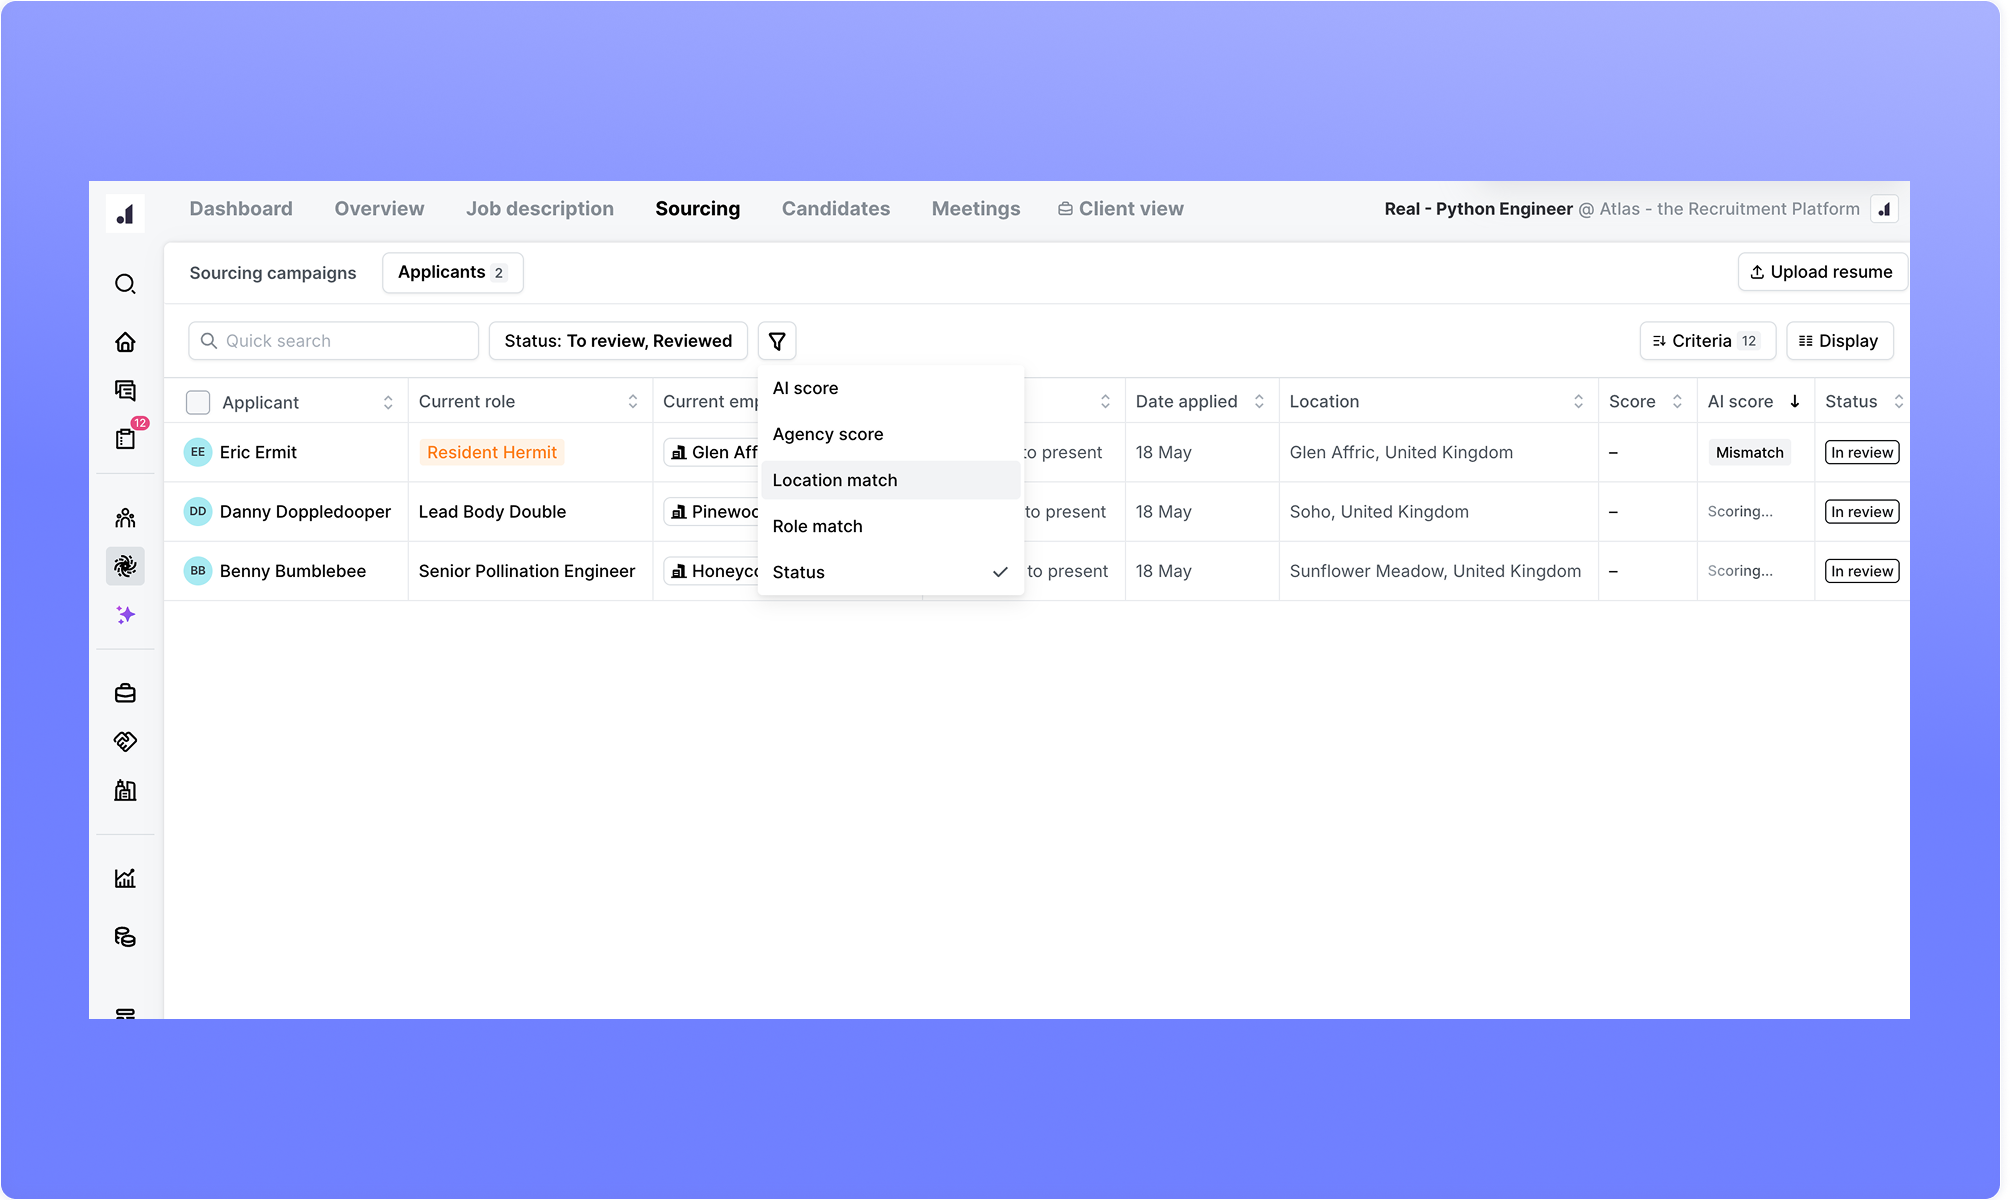
Getting the top of that list right is what Atlas People Search is built around. Atlas is an AI-powered CRM and AI-powered recruitment platform that uses agentic AI to strip admin out of the desk. Describe the person in plain language and the system builds the search for you. It reads everything the team has ever sourced or spoken to, and shows the criteria before running.
Is the problem bad search or bad candidate data?
Pick someone you know belongs in the results and check whether the search finds them. If it misses a candidate you placed two years ago, open the record. Nine times in ten the record is nearly empty.
That distinction decides what you should buy. Bad search is a vendor problem. Bad data is yours. No amount of cleverness at query time fixes a profile holding a name and a phone number. Most agencies already know which consultant’s candidates never reach the system, and have known for years.
Few teams ever measure which of the two they have. 59% of organizations do not measure data quality, according to Gartner surveys. That keeps the cost invisible until something downstream fails.
Recruiters feel it even when they cannot name it. Atlas research found that 26.67% of agency recruiters name trusting the outputs as their biggest challenge with AI, second only to integration and setup.
The durable fix is a database that maintains itself. Calls and meetings captured by an AI note taker rather than typed up on a Friday afternoon. Inbound applicants graded automatically and held outside the main database until they are worth keeping. Emails, notes, calls and transcripts folded into one searchable memory of every interaction instead of scattered across six inboxes. Finding candidates gets dramatically easier when the records being read are complete.
Frequently asked questions (FAQs) on testing AI candidate search
Long enough to run two live roles in different verticals. That is usually a few working days, not a six-week evaluation. Realism matters more than duration. A short trial on real records will tell you more than a long trial on a vendor sample set.
Yes, and most platforms will accept a representative export for the trial. Representative is the operative word. Include the duplicates, the unparsed resumes, the dead email addresses and the records holding nothing but a name and a mobile number. Those are the ones that break search.
Measure overlap with your Boolean results, unique finds on each side, shared misses, and time to a usable longlist. Then score the top twenty on whether a consultant would pick up the phone. Recall without precision creates more work for the desk rather than less.
The consultant who owns the desk, working on one of their own live roles. Vendors and ops leads both know how to phrase a query that performs well. The result only means something when the person running it is the person who will use the tool every day.
Choose a candidate you are certain belongs in the results and see whether the search returns them. If it does not, open the record and look at what is actually stored there. An empty or half-parsed profile is a data problem, and no search engine resolves it at query time.
Cleaning first makes the test less useful, because you will be running the platform on messy data in production. Test it the way you will use it. A polished sample measures the vendor’s parsing quality rather than how the search behaves on your desk.
What changes on the desk once search stops being a gamble
Agencies that get candidate search AI right tested it on their own mess. A live role, real records, a named consultant, and a baseline to beat. The decision stops hanging on which demo felt smoother. It rests on which system found the people you already owned.
What changes afterward shows up in the hours. Consultants stop rebuilding keyword matching strings for every brief. They stop scrolling past duplicates to reach the person they spoke to in March. That time returns to calls and candidate control, which is the work that actually bills. Delivering that shift is what Atlas is built for. Agentic AI handles the data work in the background, so the database stays worth searching.
Worth seeing how it behaves on your own records rather than someone else’s.